Introduction
This vignette provides an overview of the data users need to have in
order to begin making Sankey diagrams with the nsSank
package. If users already have the required data (as outlined in this
document), it is recommended they review the “Making Sankeys” vignette
to go over the workflow in more detail.
In general, this package supports two primary workflows for creating Sankey diagrams.
The original workflow, which remains available, was designed to implement the core data transformations required to produce Sankey diagrams on the Target RWE platform. It represents intermediate states using numeric identifiers and continues to be available for users who are already familiar with it.
Building on this foundation, a newer, modified workflow was developed
in Spring 2026 to improve readability and usability of
nsSank outputs. This updated approach provides more
descriptive state representations and additional functionality for users
to understand, validate, and work with their data in RStudio. In
particular the new workflow provides functions which enable users
to:
- Visualize patient flows with
plot_sankey()(generates ggplot2-based Sankey diagrams in RStudio) - Tabulate state counts at each time point with
sankey_counts_table() - Summarize patient transitions between consecutive time points with
sankey_transition_counts() - Work with subgroup-specific results using the gofl_formula argument,
with improved support for exploring and extracting individual strata
using
filter_gofl() - Prepare treatment/medication data for analysis with
create_time_varying_data()(supports leveled medications)
More details regarding these functions and their intended use cases can be found on the “Making Sankeys” vignette.
Both workflows are fully supported, and users can choose the approach that best fits their needs.
Required Data for Sankeys
To begin using the nsSank package with either workflow
mentioned above, users are required to have at minimum two types of
data: event data and cohort data. The formats
for these required data are described below.
Cohort Format
The cohort data is a wide-format data.frame
with one-record-per-id. The purpose of cohort is to provide
the nsSank package with overall id-level information. The
only required columns cohort must include are:
- Some type of
idcolumn unique to each patient - A column specifying a patient’s index date
Optional variables include:
- Baseline variables that can be used to filter the Sankeys
- Censor dates
- Absorbing state dates
“Absorbing states” are observed terminal outcomes (e.g., death) that
id’s cannot exit once entered. “Censor dates” mark when an
id can no longer be observed, but their true state remains
unknown.
Example 1: Acceptable Cohort Data
## # A tibble: 10,000 × 9
##    patient_id index_date censor_date discontinue_date death_date sex    prior_mi
##         <int> <date>     <date>      <date>           <date>     <fct>  <fct>
##  1          1 2010-06-13 2010-12-07  NA               NA         Male   No Prio…
##  2          2 2010-06-23 2011-07-06  NA               NA         Female Prior MI
##  3          3 2010-06-12 2010-10-14  NA               2011-09-29 Male   Prior MI
##  4          4 2010-06-05 2011-05-27  NA               NA         Female No Prio…
##  5          5 2010-06-06 2010-08-07  NA               NA         Male   Prior MI
##  6          6 2010-06-15 2010-09-27  NA               2010-09-23 Female No Prio…
##  7          7 2010-06-15 2011-05-21  2010-11-09       NA         Male   Prior MI
##  8          8 2010-06-04 2012-03-24  2010-07-11       NA         Female No Prio…
##  9          9 2010-06-06 2011-07-27  2010-12-17       2010-08-27 Male   No Prio…
## 10         10 2010-06-09 2011-02-01  NA               NA         Male   No Prio…
## # ℹ 9,990 more rows
## # ℹ 2 more variables: age <int>, age_cat <fct>
Event Format
The event data is a long data.frame with
one record per id, state, and start/stop days. Its purpose is to provide
event data for each id to the Sankey package, so that
nsSank can determine what state(s) each id is in at each
time point.
Variables
id_var: some sort of (typically patient) record identifier. Not all identifiers in thecohortneed to be present in theeventdata – if an identifier in the cohort data has no records inevent, that patient will be considered in the empty state until the end of follow-up or censored. However, allid’s in theeventdata should have a corresponding id-level record in thecohortfile. (i.e., a patient incohortmay or may not have any rows inevent. However, all patients with rows ineventmust have a unique row incohort)start: the start date or day of the event/state.end: the end date or day of the event/state.state: the event of interest corresponding to start/end times. Typically a treatment (i.e.PCSK9i,Ezetimibe), but can take on other forms.
Example 2: Acceptable Event Data with Non-Leveled Medications (Original Workflow)
## # A tibble: 5 × 4
##   patient_id start      end        state
##        <dbl> <date>     <date>     <chr>
## 1          1 2010-01-01 2010-01-31 a
## 2          1 2010-02-01 2010-03-31 a
## 3          1 2010-02-01 2010-03-31 b
## 4          2 2010-01-01 2010-01-31 b
## 5          2 2010-03-01 2010-04-30 b
We note that the original workflow generally assumes that states in
the events data are binary (e.g., patients are either on a
medication “a” in a given start/end time-interval; otherwise, they are
not on that medication). In contrast, the modified workflow supports
leveled-medications, so the event data is allowed to have
different levels of the same medication represented in the
state column. As an example, suppose a patient can be on
three different levels of a statin medication:
low_intensity_statin,
moderate_intensity_statin, and
high_intensity_statin. Then, the events data
can be as follows:
Example 3: Acceptable Event Data with Leveled Medications (Modified Workflow)
## # A tibble: 188 × 4
##    patient_id start      end        state
##         <int> <date>     <date>     <chr>
##  1          1 2010-05-11 2010-06-10 low_intensity_statin
##  2          1 2010-02-27 2010-05-28 a
##  3          1 2010-05-06 2010-06-05 c
##  4          2 2010-04-18 2010-06-17 c
##  5          2 2010-05-28 2010-06-27 c
##  6          2 2010-02-19 2010-05-20 c
##  7          2 2010-08-17 2010-09-16 moderate_intensity_statin
##  8          2 2010-09-12 2010-11-11 c
##  9          2 2010-11-20 2011-01-19 b
## 10          2 2010-08-23 2010-10-22 c
## # ℹ 178 more rows
Preparing Event Data: Helper Functions
This section covers a couple of helper functions that can help format
event data properly for use in nsSank.
Converting Tagged CDF’s
In this document, a tagged CDF is any data frame depicting events data in the following form:
Example 4: A tagged cdf
## # A tibble: 4 × 5
##   patient_id start_date end_date   is_a  is_b
##        <dbl> <date>     <date>     <lgl> <lgl>
## 1          1 2010-01-01 2010-01-31 TRUE  FALSE
## 2          1 2010-02-01 2010-03-31 TRUE  TRUE
## 3          2 2010-01-01 2010-01-31 FALSE TRUE
## 4          2 2010-03-01 2010-04-30 FALSE TRUE
where the logical columns represent whether a patient is on
particular medications during a specified start/stop interval (e.g.,
patient 1 above is on medication “a” from 2010-01-01 to
2010-01-31 but not on medication “b” during that time
interval).
convert_tagged_cdf is a helper function to convert
tagged CDFs to the events format needed for nsSank. The
tagged CDF that is passed through should only have tags for the states
of interest. For example, if the user has no interest in tracking a
medication “c” in the Sankey, they should remove the corresponding
indicator column is_c if present.
Calling convert_tagged_cdf on a tagged CDF will remove
any prefixes in the indicator column names. The prefix to be removed is
specified using the rmv_prefix argument. By default,
rmv_prefix = "is_", but this can be adjusted if the columns
have a different prefix.
Example 5: Converting a Tagged CDF into Acceptable Events Data
events <- convert_tagged_cdf(tagged_cdf)
events
## # A tibble: 5 × 4
## patient_id start end state
## <dbl> <date> <date> <chr>
## 1 1 2010-01-01 2010-01-31 a
## 2 1 2010-02-01 2010-03-31 a
## 3 1 2010-02-01 2010-03-31 b
## 4 2 2010-01-01 2010-01-31 b
## 5 2 2010-03-01 2010-04-30 bOverlapping Treatment Intervals
The events data supplied by users may contain
overlapping treatment intervals — either within the same treatment or
across different levels of the same treatment class. Consider the table
below, which will be used as a reference for some examples in this
section:
## # A tibble: 5 × 4
##   patient_id state                 start  stop
##        <dbl> <chr>                 <dbl> <dbl>
## 1          1 A                         0    10
## 2          1 A                         5    12
## 3          1 low_intensity_statin      0     7
## 4          1 low_intensity_statin      9    20
## 5          1 high_intensity_statin    17    25
Each row records one treatment episode: start is the
first day the patient is on that treatment and stop is the
last day. Patient 1 has two overlapping intervals for treatment
A — the rows with start = 0, stop = 10 and
start = 5, stop = 12 are both active on days 5–10. The
patient is also recorded on both low_intensity_statin and
high_intensity_statin between days 17 and 20 — an overlap
that arises because these are different levels of the same
treatment class rather than duplicate records of the same treatment.
nsSank provides three helper functions for resolving
these overlaps. Each takes a different approach:
union_eventsmerges overlapping and adjacent treatment intervals into the smallest number of continuous episodes — i.e., the output takes the union of all covered time.truncate_eventsgives precedence to later-starting intervals. When a new treatment interval begins before an existing one has ended, the existing episode is shortened to end the day before the new one starts. Only end dates change; start dates are never moved.stockpile_eventspreserves every interval’s original duration. An earlier treatment interval is left untouched, and a more recent, overlapping one is shifted forward to begin immediately after the earlier one ends. No days of coverage are lost.
All three helpers share the arguments id_var,
tx_name, tx_start, and tx_stop
for specifying columns containing patient ID’s, treatment names,
treatment start dates, and treatment stop dates, respectively.
Convention: The
tx_stopcolumn is to be interpreted as the last day a patient is ON treatment, as opposed to the first day off treatment.
The functions also accept a med_levels argument to
extend these operations across different levels of the same treatment
class (see example). Additionally,
union_events() accepts a gap argument
specifying the maximum number of days’ interruption that still counts as
the same treatment episode (default 0L). See here to see intended usage.
Interval Arrangements and Function Behavior
It turns out that two intervals can be arranged relative to one another in exactly seven structurally distinct ways — a classification formalized in James F. Allen’s (1983) interval algebra. The diagram below shows all thirteen relations Allen defined; because each relation has a mirror image (B before A is equivalent to A after B), only seven are structurally unique.
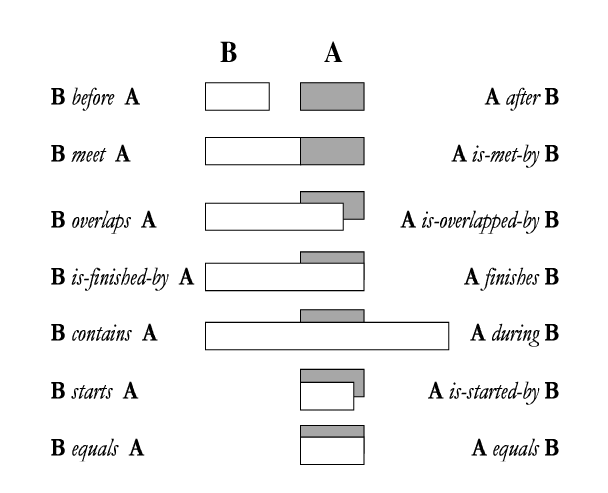
Allen’s 13 interval relations. Each row pairs a base relation with its inverse.
You do not need to already be familiar with the algebra. The diagram is included here only to establish the vocabulary — before, meets, overlaps, finishes, during, starts, and equals — that the subsections below use to name each arrangement precisely.
Each subsection below covers one of the seven arrangements: a diagram illustrates how all three helper functions handle it, with accompanying code to demonstrate usage and verify the outputs.
1. Before · After
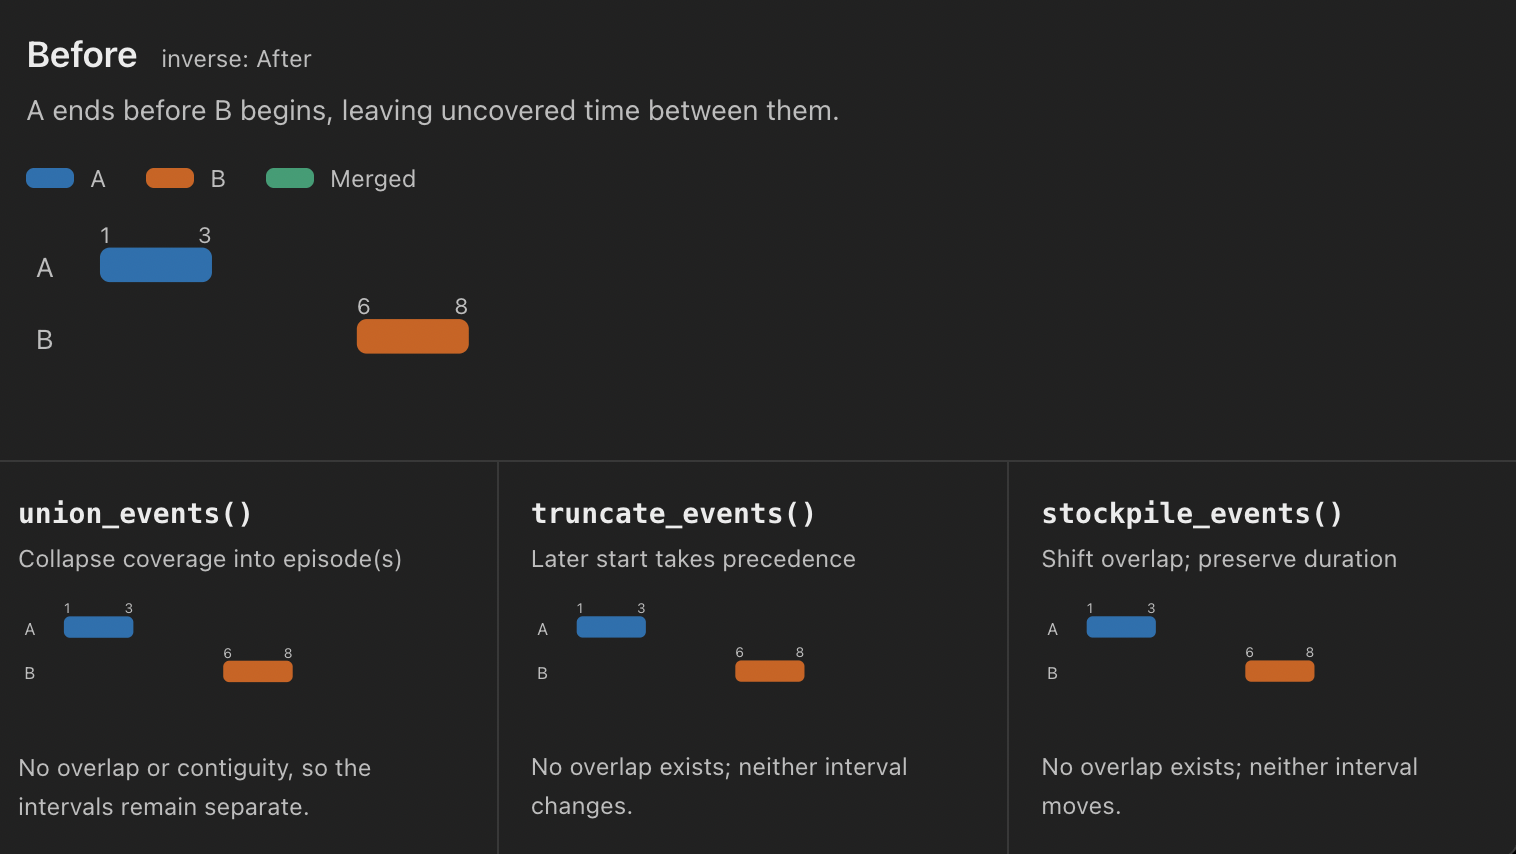
union_events(before_dat,
             tx_name = "treatment",
             tx_start = "start",
             tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 3
## 2 1 statin 6 8
truncate_events(before_dat,
                tx_name = "treatment",
                tx_start = "start",
                tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 3
## 2 1 statin 6 8
stockpile_events(before_dat,
                 tx_name = "treatment",
                 tx_start = "start",
                 tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 3
## 2 1 statin 6 82. Meets · Met by
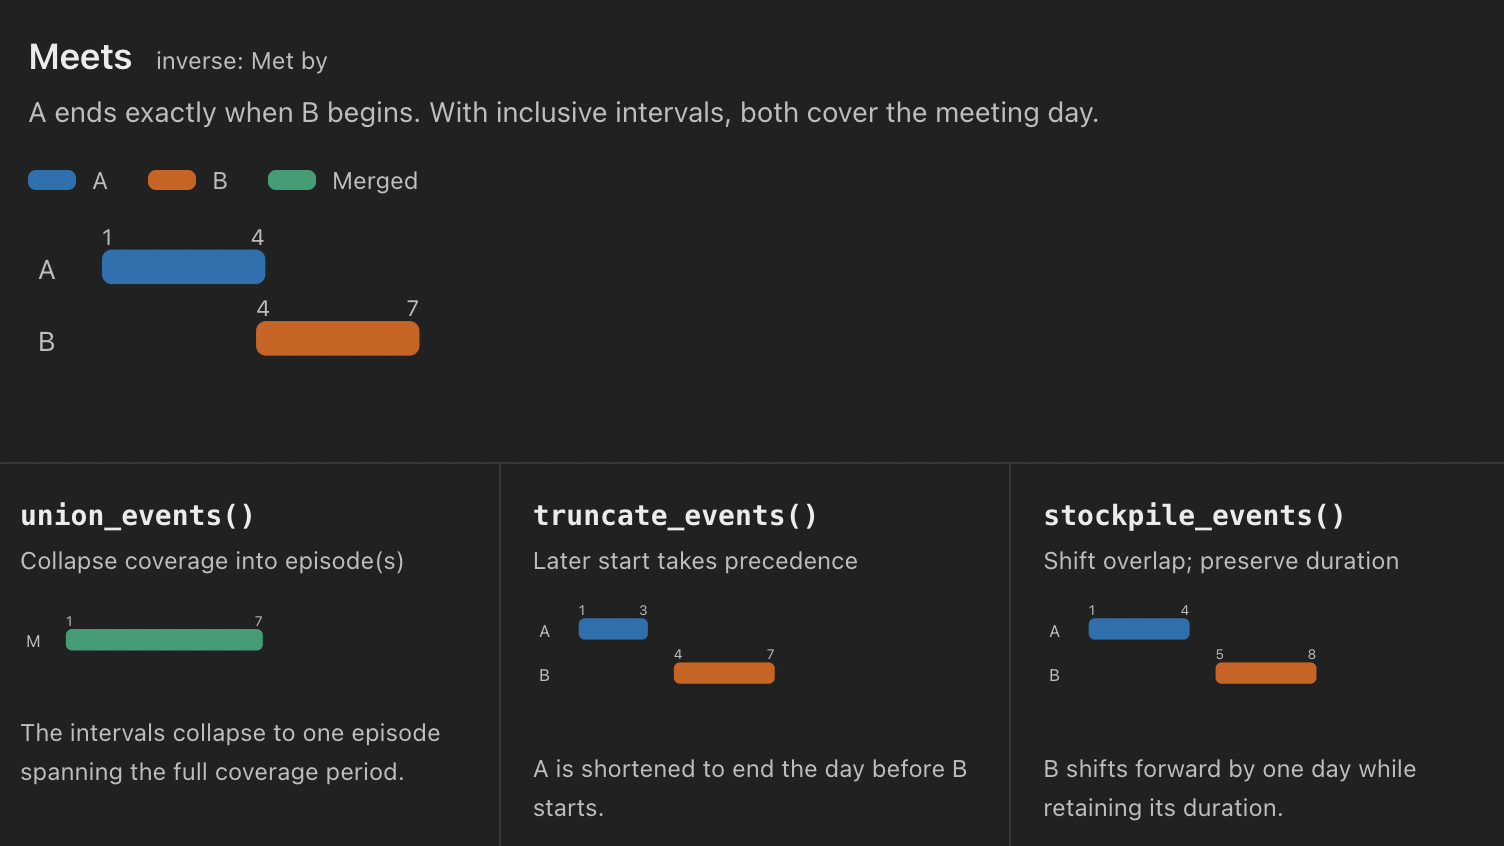
union_events(meets_dat,
             tx_name = "treatment",
             tx_start = "start",
             tx_stop = "stop")
## # A tibble: 1 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 7
truncate_events(meets_dat,
                tx_name = "treatment",
                tx_start = "start",
                tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 3
## 2 1 statin 4 7
stockpile_events(meets_dat,
                 tx_name = "treatment",
                 tx_start = "start",
                 tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 4
## 2 1 statin 5 83. Overlaps · Overlapped by
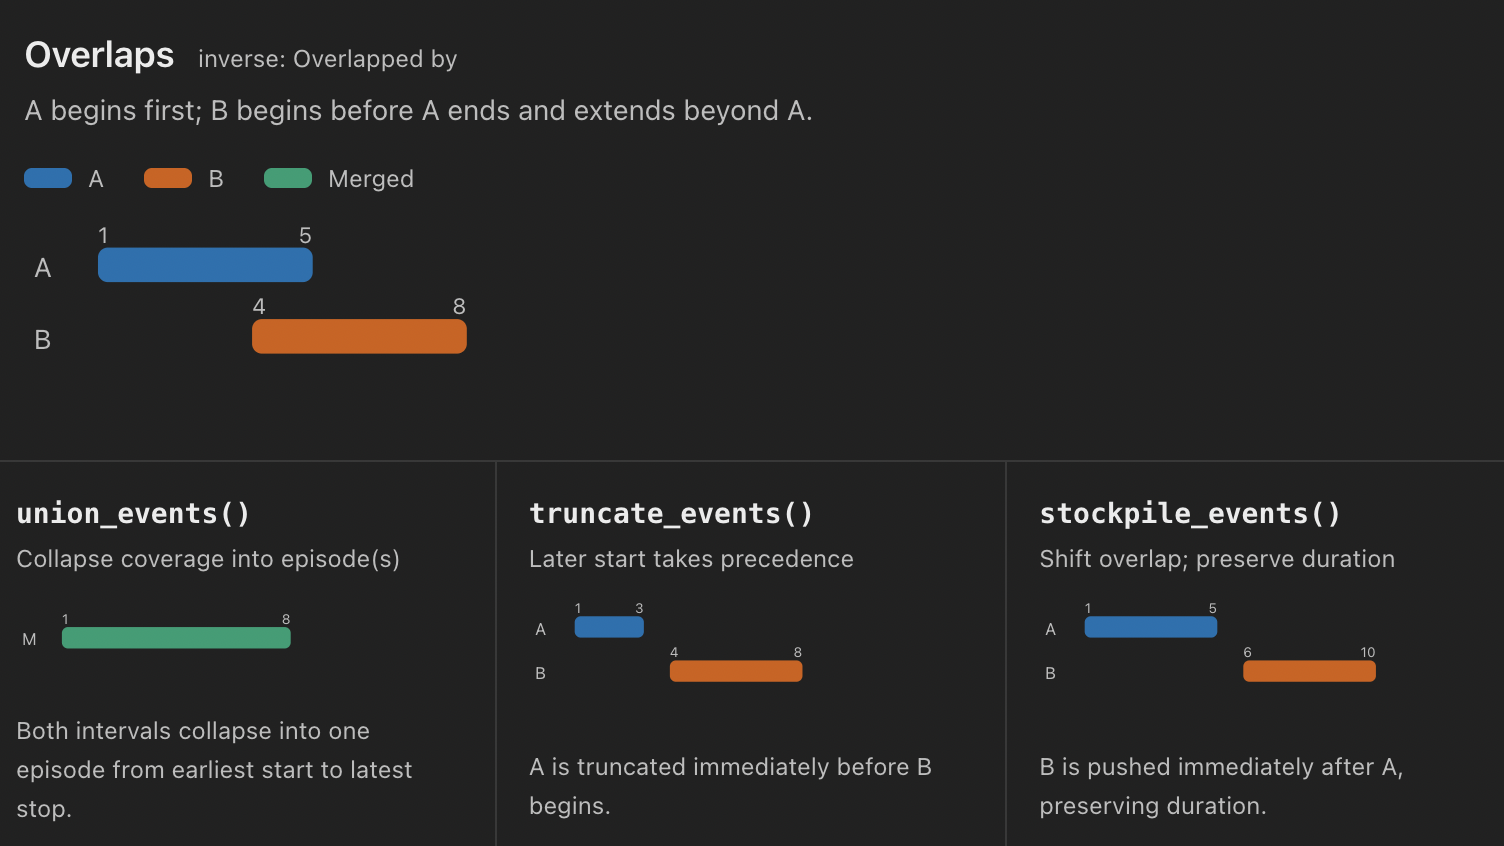
union_events(overlaps_dat,
             tx_name = "treatment",
             tx_start = "start",
             tx_stop = "stop")
## # A tibble: 1 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 8
truncate_events(overlaps_dat,
                tx_name = "treatment",
                tx_start = "start",
                tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 3
## 2 1 statin 4 8
stockpile_events(overlaps_dat,
                 tx_name = "treatment",
                 tx_start = "start",
                 tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 5
## 2 1 statin 6 104. Finishes · Finished by
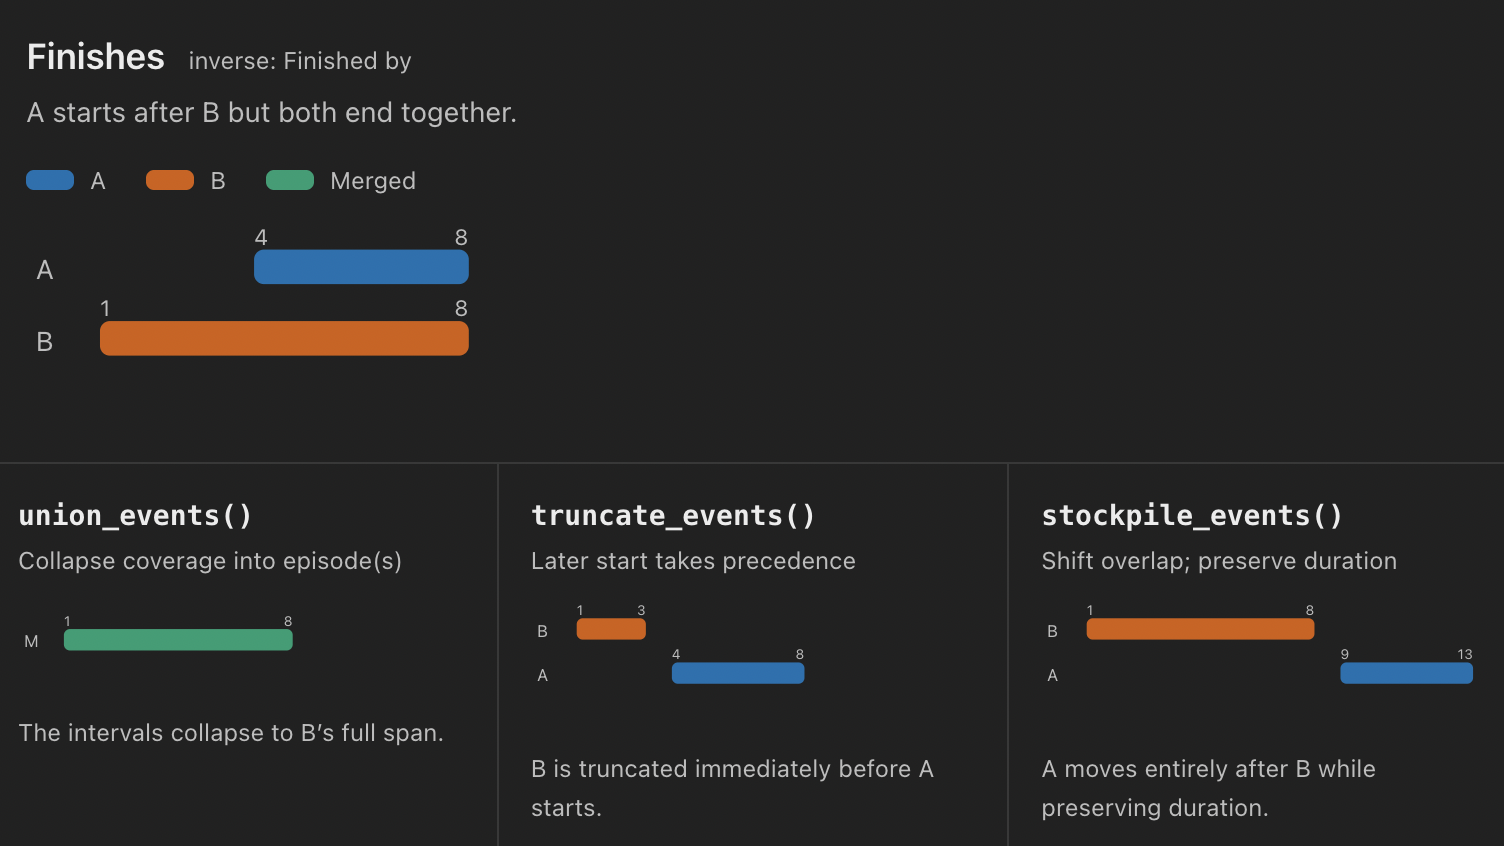
union_events(finishes_dat,
             tx_name = "treatment",
             tx_start = "start",
             tx_stop = "stop")
## # A tibble: 1 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 8
truncate_events(finishes_dat,
                tx_name = "treatment",
                tx_start = "start",
                tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 3
## 2 1 statin 4 8
stockpile_events(finishes_dat,
                 tx_name = "treatment",
                 tx_start = "start",
                 tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 8
## 2 1 statin 9 135. During · Contains
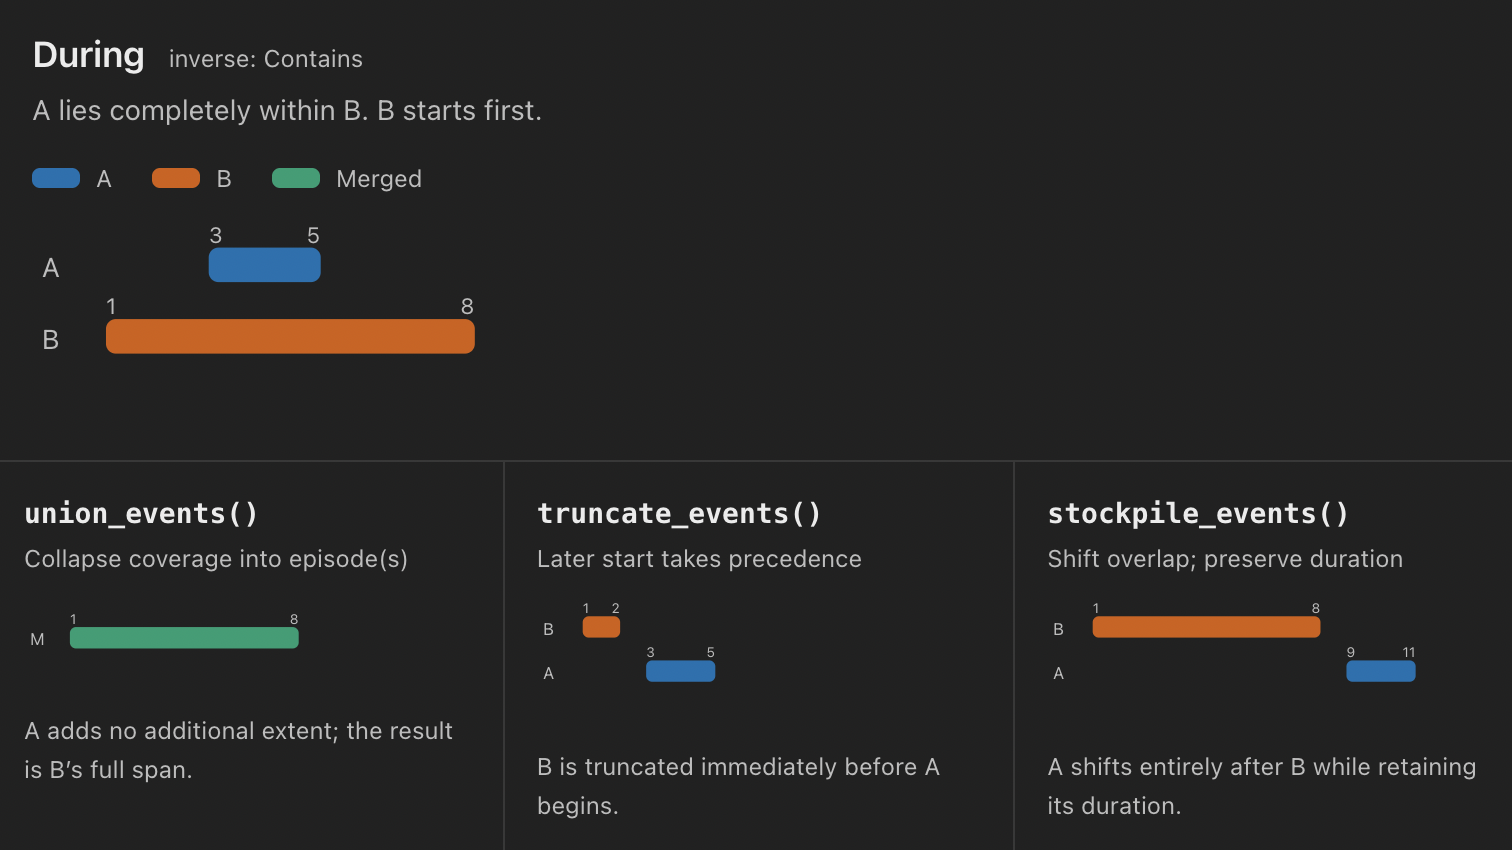
union_events(during_dat,
             tx_name = "treatment",
             tx_start = "start",
             tx_stop = "stop")
## # A tibble: 1 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 8
truncate_events(during_dat,
                tx_name = "treatment",
                tx_start = "start",
                tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 2
## 2 1 statin 3 5
stockpile_events(during_dat,
                 tx_name = "treatment",
                 tx_start = "start",
                 tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 8
## 2 1 statin 9 116. Starts · Started by
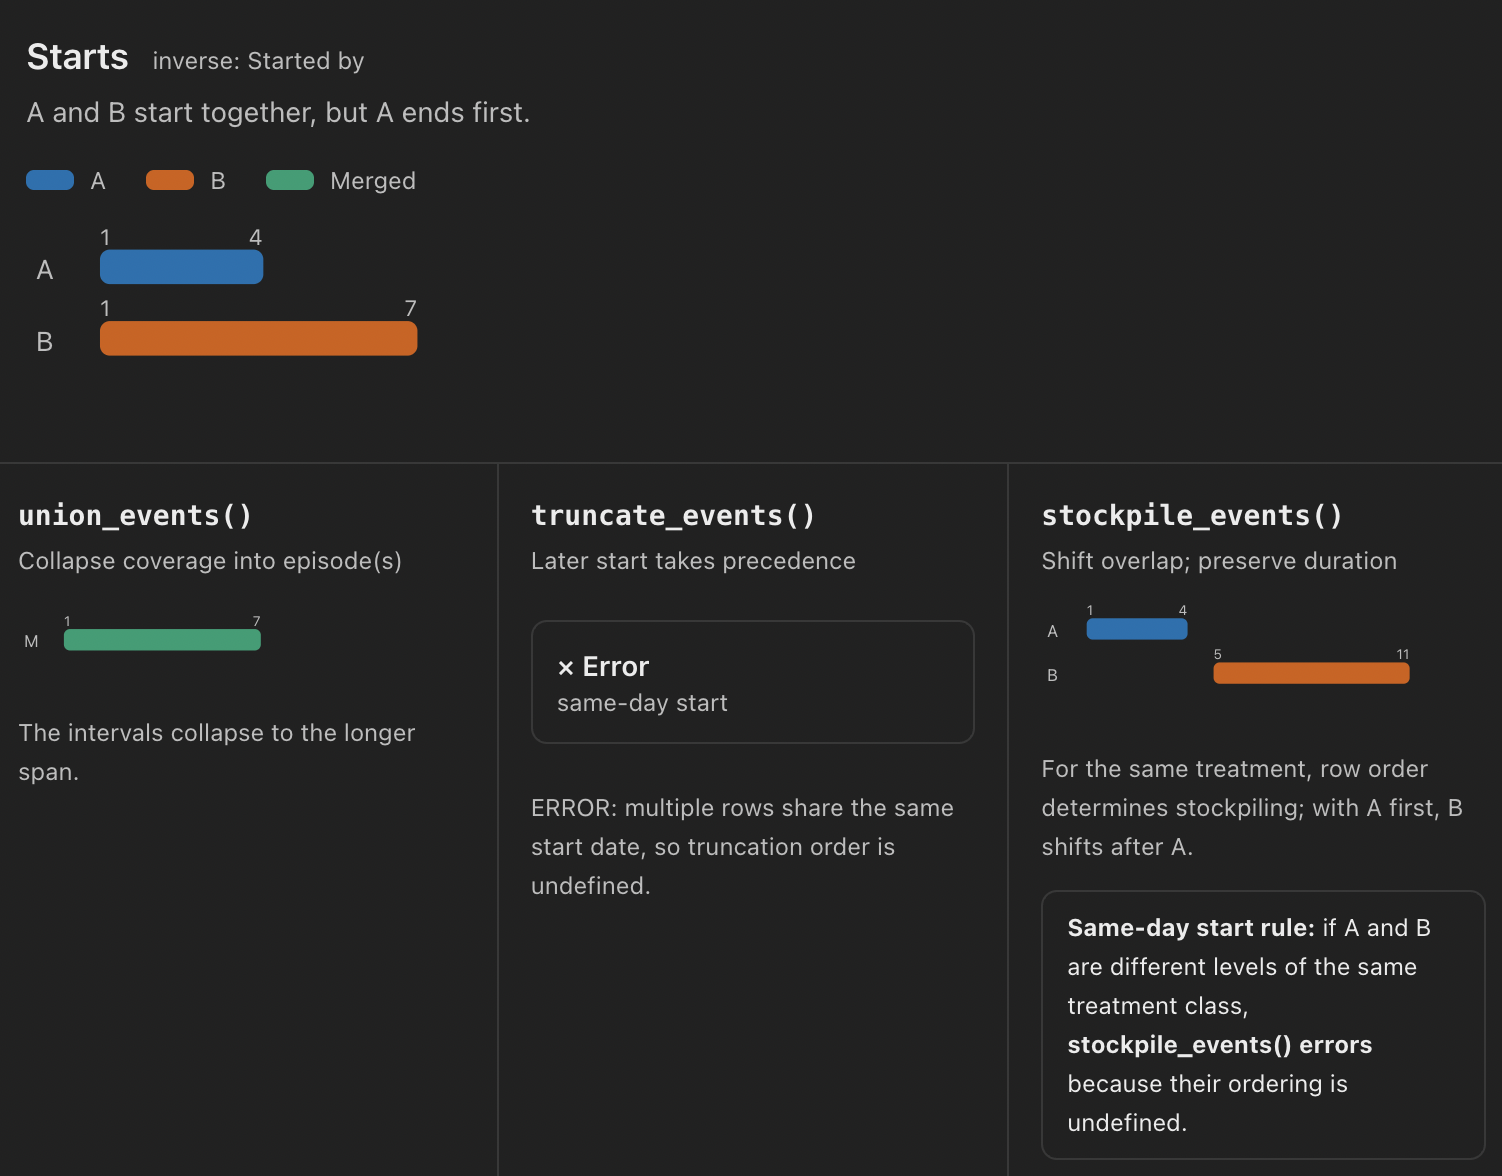
union_events(starts_dat,
             tx_name = "treatment",
             tx_start = "start",
             tx_stop = "stop")
## # A tibble: 1 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 7
truncate_events(starts_dat,
                tx_name = "treatment",
                tx_start = "start",
                tx_stop = "stop")
## Error: Truncation order is undefined when multiple rows share the same start date for the same treatment.
##
## Patient 1: statin start on 1
stockpile_events(starts_dat,
                 tx_name = "treatment",
                 tx_start = "start",
                 tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 4
## 2 1 statin 5 117. Equals
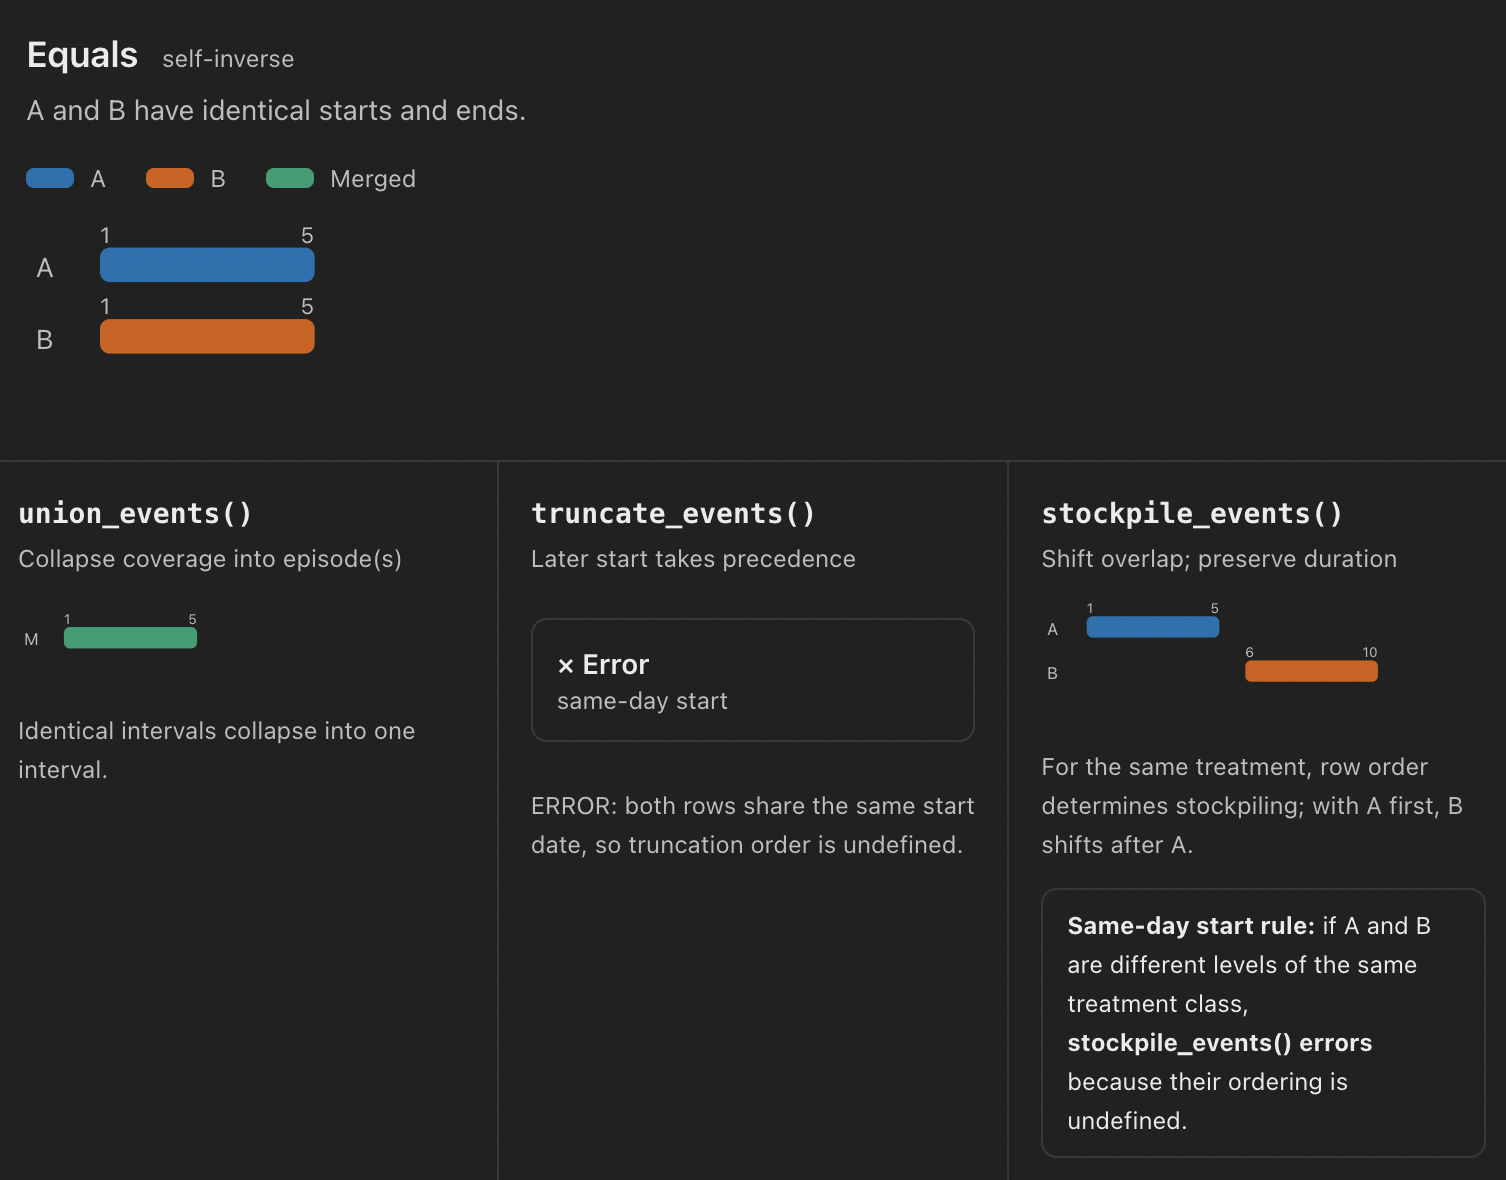
union_events(equals_dat,
             tx_name = "treatment",
             tx_start = "start",
             tx_stop = "stop")
## # A tibble: 1 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 5
truncate_events(equals_dat,
                tx_name = "treatment",
                tx_start = "start",
                tx_stop = "stop")
## Error: Truncation order is undefined when multiple rows share the same start date for the same treatment.
##
## Patient 1: statin start on 1
stockpile_events(equals_dat,
                 tx_name = "treatment",
                 tx_start = "start",
                 tx_stop = "stop")
## # A tibble: 2 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 5
## 2 1 statin 6 10Example: Bridging gaps with the gap argument
By default, union_events() only merges intervals that
overlap or are exactly contiguous (no uncovered day between them). The
gap argument relaxes this: setting gap = 2L
tells the function to merge any two intervals separated by two days or
fewer, treating the interruption as part of the same treatment episode
rather than the start of a new one. Using the same before
arrangement from section 1 — A [1, 3] and B
[6, 8], separated by a two-day gap — the two intervals now
collapse into one:
union_events(before_dat,
             tx_name = "treatment",
             tx_start = "start",
             tx_stop = "stop",
             gap = 2L)
## # A tibble: 1 × 4
## patient_id treatment start stop
## <int> <chr> <dbl> <dbl>
## 1 1 statin 1 8gap only affects union_events();
truncate_events() and stockpile_events() do
not have a gap argument.
Example: Resolving overlaps across treatment levels with
med_levels
By default, all three functions operate independently within each
distinct value of the tx_name column. Overlaps between rows
with different treatment names are left unresolved — which is
the correct behavior when those rows truly represent separate
treatments. When different names are actually levels of the same
treatment class, however, the med_levels argument is used
to declare that relationship and extend the overlap resolution across
them.
We use the example_data from the start of this
section:
## # A tibble: 5 × 4
##   patient_id state                 start  stop
##        <dbl> <chr>                 <dbl> <dbl>
## 1          1 A                         0    10
## 2          1 A                         5    12
## 3          1 low_intensity_statin      0     7
## 4          1 low_intensity_statin      9    20
## 5          1 high_intensity_statin    17    25
The statin rows for low_intensity_statin and
high_intensity_statin overlap between days 17 and 20.
Passing
med_levels = list(statin = c("low_intensity_statin", "high_intensity_statin"))
tells each function to treat those rows as belonging to the same
class:
union_events(example_data,
             med_levels = list(statin = c("low_intensity_statin",
                                          "high_intensity_statin")),
             tx_name = "state",
             tx_start = "start",
             tx_stop = "stop")
## # A tibble: 3 × 4
## patient_id trt_class start stop
## <dbl> <chr> <dbl> <dbl>
## 1 1 A 0 12
## 2 1 statin 0 7
## 3 1 statin 9 25The previously overlapping statin rows —
low_intensity_statin [9, 20] and
high_intensity_statin [17, 25] — are merged
into a single statin episode [9, 25]. The
earlier low_intensity_statin interval [0, 7]
is separated from it by a one-day gap (day 8 is uncovered) and remains a
distinct episode. Note that the level-specific names are replaced by the
class name in the output’s trt_class column — once a
med_levels union has been taken, the original level
information is not retained.
truncate_events(example_data,
                med_levels = list(statin = c("low_intensity_statin",
                                             "high_intensity_statin")),
                tx_name = "state",
                tx_start = "start",
                tx_stop = "stop")
## # A tibble: 5 × 4
## patient_id state start stop
## <dbl> <chr> <dbl> <dbl>
## 1 1 A 0 4
## 2 1 A 5 12
## 3 1 high_intensity_statin 17 25
## 4 1 low_intensity_statin 0 7
## 5 1 low_intensity_statin 9 16With truncate_events(), the
low_intensity_statin interval ending on day 20 is shortened
to end on day 16, immediately before high_intensity_statin
starts on day 17. The level names are preserved in the output since no
merging has taken place.
stockpile_events(example_data,
                 med_levels = list(statin = c("low_intensity_statin",
                                              "high_intensity_statin")),
                 tx_name = "state",
                 tx_start = "start",
                 tx_stop = "stop")
## # A tibble: 5 × 4
## patient_id state start stop
## <dbl> <chr> <dbl> <dbl>
## 1 1 A 0 10
## 2 1 A 11 18
## 3 1 high_intensity_statin 21 29
## 4 1 low_intensity_statin 0 7
## 5 1 low_intensity_statin 9 20With stockpile_events(), the
high_intensity_statin interval [17, 25] is
shifted forward to begin immediately after the
low_intensity_statin interval ends on day 20, resulting in
a new interval of [21, 29].
Splitting Leveled and Unleveled Treatment Classes
Many of the functions showcased in the previous section perform the
same operation on both leveled and unleveled treatments. However, in
order to provide users with complete flexibility and control over how
they wish to manage their events data, a
split_treatment_classes function has been added which
allows users to map treatment classes to their constituent levels and
return 2 different datasets:
- A
leveled_trtsdataset which consists of only leveled medication states specified by the user - A
non_leveled_trtsdataset consisting of all other medication states
As an example, suppose we wanted to split our previous
example_data into a dataset containing only
high_intensity_statin and low_intensity_statin
states and a dataset consisting of all other unleveled treatments:
split <- split_treatment_classes(example_data,
                                 med_levels = list(statin = c("low_intensity_statin",
                                                              "high_intensity_statin")),
                                 tx_name = "state"
                                 )
Here, split is a named list from which our desired
datasets may be extracted:
leveled_treatments <- split[["leveled_trts"]]
leveled_treatments
## # A tibble: 3 × 5
## patient_id state start stop trt_class
## <dbl> <chr> <dbl> <dbl> <chr>
## 1 1 low_intensity_statin 0 7 statin
## 2 1 low_intensity_statin 9 20 statin
## 3 1 high_intensity_statin 17 25 statin
unleveled_treatments <- split[["non_leveled_trts"]]
unleveled_treatments
## # A tibble: 2 × 5
## patient_id state start stop trt_class
## <dbl> <chr> <dbl> <dbl> <chr>
## 1 1 A 0 10 A
## 2 1 A 5 12 AFormatting Events for Sunbursts
The sunburst requires ordered events, regardless of time. The
ansible function converts data in an event-time format
(e.g., the CDF, where each row uniquely identifies a single event with
start and stop times) to an interval format, where, within a patient,
time is separated into mutually exclusive time intervals that capture
all events that happened in that interval.
ansible requires event data converted from the CDF. By
default ansible will apply stockpile_events to
the data in order to function properly. If the data are already
stockpiled, can indicate using stockpile = F to skip this
step.
Below, we convert the example data from example 5 to the
ansible format. By default, gap = 1L is
applied.
events <- convert_tagged_cdf(tagged_cdf)
events
## # A tibble: 5 × 4
## patient_id start end state
## <dbl> <date> <date> <chr>
## 1 1 2010-01-01 2010-01-31 a
## 2 1 2010-02-01 2010-03-31 a
## 3 1 2010-02-01 2010-03-31 b
## 4 2 2010-01-01 2010-01-31 b
## 5 2 2010-03-01 2010-04-30 b
data <- ansible(events)
data
## # A tibble: 4 × 4
## patient_id start end state
## <dbl> <date> <date> <list>
## 1 1 2010-01-01 2010-01-31 <chr [1]>
## 2 1 2010-02-01 2010-03-31 <chr [2]>
## 3 2 2010-01-01 2010-01-31 <chr [1]>
## 4 2 2010-03-01 2010-04-30 <chr [1]>Time is split into the exclusive intervals where events happen – from
2010-02-01 - 2010-03-30, the A and
B states overlapped for patient 1:
## [1] "a" "b"Converting data to this format allows us to (1) filter once on single time to get all events associated with that time, and (2) uniquely order the pattern of events.